AWS Global Infrastructure: Why Regions and Availability Zones Matter
Looking to build resilient cloud applications that stay online even during outages? AWS’s global infrastructure is the foundation you need to understand.
For cloud architects, DevOps engineers, and IT managers planning mission-critical workloads, knowing how AWS organizes its data centers worldwide can make or break your disaster recovery strategy.
This guide explains how AWS Regions provide geographic isolation, how Availability Zones enable high availability, and the business advantages of designing applications across multiple locations.
We’ll explore practical strategies for implementing multi-region architectures that balance performance and cost while maximizing uptime.
Understanding AWS Global Infrastructure
A. The building blocks of AWS cloud services
When you start exploring AWS, you’ll quickly discover it’s built on a massive physical foundation spanning the globe. At its core, AWS infrastructure consists of data centers – physical buildings packed with servers, storage, and networking equipment that power all those cloud services you use daily.
These data centers aren’t randomly scattered – they’re strategically organized into Availability Zones (AZs). Think of an AZ as a cluster of data centers in the same geographic area, designed to be isolated from failures in other zones. When you launch an EC2 instance, you’re actually running it in one of these physical locations.
B. How AWS organizes its worldwide network
AWS groups these Availability Zones into Regions – geographic areas like US East (N. Virginia) or Asia Pacific (Tokyo). Each Region typically contains 3-6 AZs, connected by high-speed, low-latency networks.
You’ll notice this organization when you deploy resources – you always choose a specific Region first. This matters because:
- Your data stays in the Region you select (unless you configure otherwise)
- Services and features vary by Region
- Pricing differs between Regions
- Regions operate independently from each other
This tiered structure gives you incredible flexibility when designing applications.
C. Impact on application performance and reliability
This global infrastructure directly affects how your applications perform. By placing resources closer to your users, you’ll reduce latency dramatically. A user in Sydney accessing your application from an Asia Pacific Region will experience much faster response times than if your resources were only in North America.
The multi-AZ design also gives you built-in redundancy. When you spread your workload across multiple AZs, you’re protected against local disasters. If a power outage or natural disaster hits one AZ, your application can continue running from the others.
D. Key components beyond regions and availability zones
The AWS global infrastructure extends beyond just Regions and AZs:
- Edge Locations: These smaller facilities host AWS CloudFront and Route 53 services, bringing content delivery closer to users worldwide. You’ll find many more Edge Locations than Regions.
- Local Zones: These extensions of Regions place compute, storage and database resources even closer to large population centers for latency-sensitive applications.
- Wavelength Zones: Designed specifically for ultra-low-latency applications, these zones integrate AWS compute and storage services within 5G networks.
- Outposts: This service brings AWS infrastructure directly to your on-premises data center, giving you the same tools and APIs locally.
By understanding how these components work together, you can build truly resilient applications that leverage AWS’s global footprint.
AWS Regions Explained
A. What defines an AWS Region
An AWS Region is essentially a physical location where Amazon has clustered multiple data centers. Each Region is completely isolated from other Regions, giving you true geographic separation. This separation is crucial – it means that if something goes wrong in one Region, it won’t affect your resources in another.
When you’re working with an AWS Region, you’re actually interacting with a full-service infrastructure environment that has its own deployment of AWS services, APIs, and network connectivity. Each Region is designed to be completely independent, which gives you maximum reliability for your applications.
B. Strategic locations and global coverage
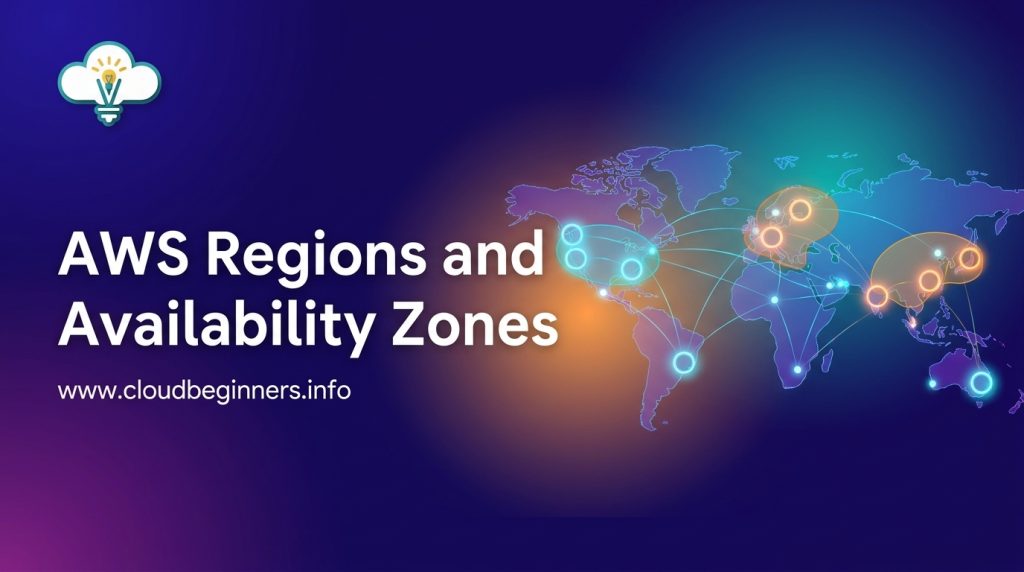
AWS has strategically placed its Regions around the world to serve you better. Currently, you can access over 30 launched Regions with nearly 100 Availability Zones.
The global coverage looks something like this:
| Continent | Number of Regions | Example Locations |
|---|---|---|
| North America | 7 | Ohio, Oregon, Northern Virginia |
| South America | 2 | São Paulo, Buenos Aires |
| Europe | 8 | Ireland, Frankfurt, London |
| Asia Pacific | 9 | Tokyo, Seoul, Singapore |
| Middle East | 2 | Bahrain, UAE |
| Africa | 1 | Cape Town |
This widespread coverage ensures you can place your workloads close to your users, reducing latency and improving user experience.
C. Region selection criteria for your workloads
Picking the right Region for your workloads isn’t just a technical decision – it’s strategic. Here’s what you should consider:
- Proximity to users: The closer your application is to users, the faster it will respond.
- Compliance requirements: Some data must stay within specific geographic boundaries due to regulations.
- Service availability: Not all AWS services are available in every Region.
- Disaster recovery needs: Using multiple Regions creates resilience against regional outages.
- Cost considerations: Pricing varies between Regions.
The best choice balances all these factors according to your specific needs.
D. Regional service availability differences
Not all AWS services are created equal across Regions. The newest services typically launch in the US East (N. Virginia) Region first before expanding to others.
Some specialized services might only be available in select Regions. For example, AWS Wavelength (for ultra-low latency applications) is only available in specific locations with 5G network partnerships.
Before committing to a Region, you should check the AWS Regional Services page to confirm that all the services you need are supported. This prevents surprises when you’re halfway through implementation and discover a critical service isn’t available.
E. Cost variations across regions
Your AWS bill can look dramatically different depending on which Region you choose. Price variations exist for practically all AWS services across Regions.
For instance, running the same EC2 instance in São Paulo might cost 20% more than in Virginia. These differences stem from various factors:
- Local infrastructure costs
- Market conditions
- Supply and demand dynamics
- Regional taxes and regulatory requirements
Data transfer costs also vary, especially for traffic between Regions. Moving data between Regions incurs charges in both directions, which can add up quickly for data-intensive applications.
To optimize your cloud spending, run cost comparisons across candidate Regions using the AWS Pricing Calculator before deployment.
Availability Zones: The Redundancy Foundation
A. Physical and logical separation between AZs
When you’re building on AWS, you’re actually tapping into one of the most sophisticated infrastructure designs in the world. Availability Zones aren’t just fancy names; they’re completely separate data centers with their own power, cooling, and networking.
Think about it: each AZ sits miles away from others in the same region but remains connected through ultra-low-latency links. This means your applications can span multiple locations without users noticing any difference in performance.
What makes this setup powerful is that while these facilities are physically isolated from disasters like floods or power outages, they’re logically united in your AWS console. You don’t have to manage multiple environments—AWS handles the complexity behind the scenes.
B. How AZs prevent cascading failures
Remember that server crash that took down your entire application last year? With proper AZ architecture, that becomes a thing of the past.
If one data center has issues, your workloads automatically shift to healthy AZs. No dramatic failovers, no panicked midnight calls; just continuous operation.
The magic happens because:
- Resources in one AZ can fail without affecting others
- Network paths are redundant between zones
- Power supplies are completely independent
- Your data can replicate across zones in near real-time
C. Best practices for multi-AZ deployments
Getting AZ redundancy right isn’t automatic; you need to design for it. Here’s how to make the most of AWS’s infrastructure:
- Spread everything important across at least two AZs;databases, application servers, load balancers, everything.
- Use services that handle AZ distribution for you like Auto Scaling Groups, RDS Multi-AZ, and ELB.
- Test your failover regularly. Don’t wait for an actual disaster to find out if your architecture works.
- Monitor from outside your primary region so you’ll know if an entire region becomes unreachable.
- Keep AZ-awareness in your app code to handle retries and fallbacks intelligently.
Business Benefits of AWS’s Distributed Architecture
A. Meeting compliance and data sovereignty requirements
When you’re expanding your business globally, data regulations become a major headache. AWS’s regional architecture is your secret weapon here. You can keep your European customers’ data in EU regions (like Frankfurt or Dublin), ensuring you’re GDPR-compliant without jumping through legal hoops.
Think about it – your healthcare app can store patient data in domestic regions while still serving users worldwide. No more worrying about violating data residency laws or explaining to regulators why sensitive information is crossing borders.
AWS makes this easy with region-specific IAM policies. You can explicitly control where your data lives and who can access it from which locations. This granular control means you’re not constantly walking a compliance tightrope.
B. Disaster recovery capabilities
Disasters happen. But with AWS’s distributed architecture, you’re not putting all your eggs in one basket.
You can implement cross-region backups that keep your business running even if an entire region goes down. Picture this: your primary workload runs in US-East-1, while US-West-2 stands ready with replicated data and infrastructure that can spin up in minutes if needed.
AWS gives you multiple DR strategies:
| Strategy | Recovery Time | Use Case |
|---|---|---|
| Backup & Restore | Hours | Non-critical workloads |
| Pilot Light | ~10 minutes | Important applications |
| Warm Standby | Minutes | Business-critical systems |
| Multi-Site Active/Active | Immediate | Mission-critical operations |
Your finance team will appreciate that you’re only paying full price for active resources – standby environments can be minimally provisioned until needed.
C. Reducing latency for global user bases
Your customers hate waiting. When your app feels sluggish, they bounce – fast.
AWS’s global infrastructure lets you place resources closer to users, dramatically cutting load times. Your US customers can hit Virginia servers while Asian users connect to Singapore or Tokyo. This proximity slashes latency from seconds to milliseconds.
CloudFront takes this further by caching content at edge locations – over 400 worldwide. Your images, videos, and static assets load lightning-fast regardless of where users are located.
For database-heavy applications, you can use Global Tables in DynamoDB or Aurora Global Database to keep data synchronized across regions while still providing local read access.
The real-world impact? Your Australian users no longer feel like second-class citizens because they’re getting the same snappy experience as everyone else.
D. Scaling across regions for peak performance
Traffic spikes can crush your infrastructure. But with AWS’s multi-region capability, you can build applications that scale not just up, but out across geographical boundaries.
When your US e-commerce site gets hammered during Black Friday, you can dynamically shift traffic to underutilized regions in Europe or Asia. Global Accelerator helps you intelligently route users to the healthiest endpoints with the lowest latency.
You can implement regional auto-scaling groups that grow independently based on local demand patterns. Your application scales precisely where needed without overprovisioning everywhere.
This regional isolation also gives you freedom to experiment. Want to test a new feature without risking your entire user base? Roll it out in a single region first, measure the impact, then expand globally when you’re confident.
Real-World Implementation Strategies
A. Determining the optimal region for your primary workload
Picking the right AWS region isn’t just a technical checkbox it’s a strategic decision that impacts everything downstream. Start by mapping your users’ locations. If most of your customers are in Europe, placing your workload in eu-west-1 (Ireland) will deliver better performance than us-east-1 (Virginia).
Regulatory requirements might force your hand too. Need to keep data in Canada? ca-central-1 is your only option. Have GDPR concerns? Stick to EU regions.
Don’t overlook pricing; it varies significantly between regions. Running the same workload in São Paulo costs more than in North Virginia. For compute-heavy applications, you might save 15-20% just by choosing wisely.
Feature availability matters too. Not all AWS services launch simultaneously across regions. If you need the latest machine learning tools, us-east-1 typically gets them first.
B. Multi-region vs. multi-AZ architectures: choosing the right approach
Here’s the honest truth: multi-region deployments are complex and expensive, but multi-AZ setups might not provide enough protection for your critical systems.
| Aspect | Multi-AZ | Multi-Region |
|---|---|---|
| Cost | Lower | 2-3x higher |
| Setup complexity | Moderate | High |
| Recovery time | Minutes | 10+ minutes |
| Protection level | Zone failures | Regional disasters |
| Data consistency | Easier | Challenging |
Multi-AZ works great for most applications; it protects against power outages, network issues, and hardware failures. AWS handles AZ failover automatically for many managed services.
Go multi-region when you need:
- Global presence with low latency
- Protection against entire region failures
- Compliance with data sovereignty requirements
- Near-zero recovery time objectives
C. Cost-effective redundancy planning
Building redundancy doesn’t mean doubling your AWS bill. Smart redundancy planning focuses on what matters.
Tier your applications first. Mission-critical systems deserve full redundancy across regions. For internal tools, multi-AZ might be enough. Some non-critical workloads might not need redundancy at all.
Use AWS services that have redundancy built-in. DynamoDB global tables and Aurora Global Database handle replication for you, saving engineering time and reducing errors.
Reserved Instances and Savings Plans work across AZs in the same region—perfect for multi-AZ setups. For multi-region, consider Compute Savings Plans that apply across regions.
S3 already replicates data across multiple AZs by default. For regional redundancy, S3 Cross-Region Replication is surprisingly affordable compared to the protection it provides.
D. Testing failover between availability zones
Hoping your failover works isn’t a strategy. You need to know it works.
Set up regular chaos engineering exercises. Tools like AWS Fault Injection Simulator let you deliberately introduce failures to test your systems’ resilience. Start small by taking down single EC2 instances, then graduate to failing entire AZs.
Document your expected Recovery Time Objective (RTO) and Recovery Point Objective (RPO), then measure actual performance during tests. The gap tells you where to focus improvements.
Test database failover specifically. RDS and Aurora failovers have nuances that might surprise you during a real emergency.
The best architectures make failover invisible to users. Route 53 health checks combined with Application Load Balancers can automatically redirect traffic away from troubled zones.
The strategic design of AWS’s global infrastructure represents a critical advantage for businesses operating in the cloud.
By leveraging multiple regions and availability zones, organizations can create resilient architectures that maintain high availability while meeting compliance requirements for data sovereignty.
The distributed nature of this infrastructure enables companies to optimize for both performance and disaster recovery, ensuring applications remain accessible even during regional disruptions.
As you plan your AWS deployment strategy, consider starting with multi-AZ implementations within a single region before expanding to multi-region architectures as your business needs evolve.
Remember that each additional layer of geographic redundancy brings both enhanced resilience and increased complexity.
By thoughtfully aligning your infrastructure choices with your specific business requirements for availability, latency, and compliance, you’ll maximize the value of AWS’s global footprint while maintaining operational efficiency.
I’ve also built a platform that shows you how to build the right hands-on cybersecurity skills to help businesses achieve their cloud security goals while you build the career you love for a better, higher-paying reward. Check it out here and start working on projects that will help you get hired.
The Author